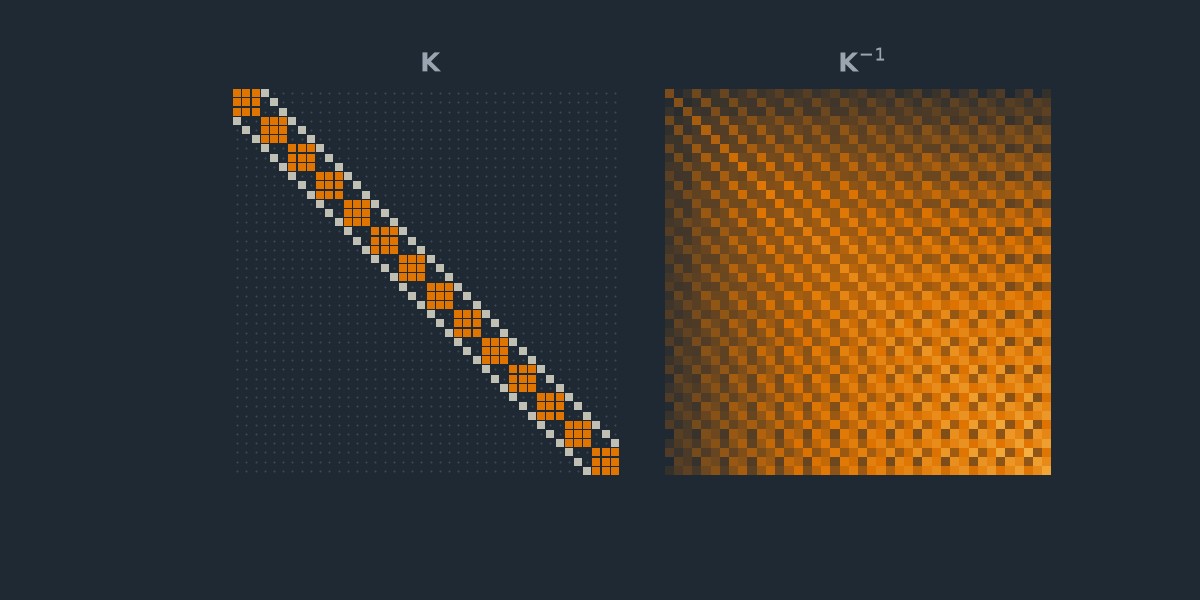
A major part of my recent work develops computationally efficient Bayesian methods for high-dimensional state space models. These models are widely used in macroeconomics for nowcasting, handling missing and mixed-frequency data, modeling time variation, and producing density forecasts. The key practical challenge is computation: naive Kalman-based approaches can become prohibitively expensive as the dimension grows or when missing data patterns are complex.
Start Here
For beginners, chapters 6 and 7 of my teaching notes on linear and nonlinear state space models give a gentle introduction. Chan and Strachan (2023) survey modern Bayesian state space models in macroeconomics and discuss scalable computation.
The code for Bayesian state space models is collected on GitHub in statespace-toolkit, which archives fourteen packages from my code page as they are distributed there and factors their shared machinery into a documented library: the precision sampler and the integrated likelihood of Chan and Jeliazkov (2009), the missing-data draw of Chan, Poon and Zhu (2023) and the accept-reject Metropolis-Hastings step of Chan (2017). Its ten MATLAB examples, from a local level model to a TVP-MIDAS regression, are a good way to learn the models and methods, and its tutorials apply them to one empirical question each:
- Which Unobserved Components Model Should I Use for Inflation?
- Which Parameters of a GDP Nowcasting Model Should Vary over Time?
The toolkit's how-to guides show how to turn a model's equations into working MATLAB code with its core functions, step by step, on small examples with generated data:
- How to Draw the States of an Unobserved Components Model
- How to Estimate a State Space Model by Gibbs Sampling
- How to Compute the Integrated Likelihood of a State Space Model
Each code page names the paper to cite, and the toolkit's CITING.md maps each method to its paper.
Precision-Based Computation for State Space Models
Efficient Simulation and Integrated Likelihood Estimation in State Space Models
Joshua Chan and Ivan Jeliazkov (2009), International Journal of Mathematical Modelling and Numerical Optimisation, 1(1/2): 101-120
[ Journal Version | Working Paper | Code | Toolkit ]
Chan and Jeliazkov (2009)
develop a conceptually transparent derivation of the posterior distribution of the state vector that leads to a modular and
scalable precision-based simulation algorithm. The same framework also yields a convenient approach for evaluating the
integrated likelihood (marginal of the states), which is useful for model comparison and hyperparameter selection. Many of
the papers below build on this algorithm.
The Stochastic Volatility in Mean Model with Time-Varying Parameters: An Application to Inflation Modeling
Joshua Chan (2017), Journal of Business and Economic Statistics, 35(1): 17-28
[ Journal Version | Working Paper | Code | Toolkit ]
Chan (2017) develops an accept-reject Metropolis-Hastings (ARMH) algorithm for log-volatilities whose
conditional distribution is not Gaussian. Its proposal is a Gaussian approximation centered at the mode.
Newton-Raphson updates locate the mode quickly because the Hessian is a band matrix, and the precision
sampler of Chan and Jeliazkov (2009) draws the candidates. The paper applies the algorithm to the
stochastic volatility in mean model with time-varying parameters in the conditional mean, where the
volatility enters both the conditional mean and the conditional variance, and estimates the model for
US, UK and German inflation.
High-Dimensional State Space Models with Missing and Mixed-Frequency Data
High-Dimensional Conditionally Gaussian State Space Models with Missing Data
Joshua Chan, Aubrey Poon and Dan Zhu (2023), Journal of Econometrics, 236(1): 105468
[ Journal Version | Working Paper | Tutorial | Video ]
Chan, Poon and Zhu (2023)
develop computational methods for high-dimensional conditionally Gaussian state space models with missing observations,
exploiting sparse/banded precision structures to draw missing values and latent states efficiently. This is particularly useful
for macroeconomic datasets with ragged edges and mixed frequencies.
Time-Varying Parameter MIDAS Models: Application to Nowcasting US Real GDP
Joshua Chan, Aubrey Poon and Dan Zhu (2026), Journal of Econometrics, forthcoming
[ Journal Version | Working Paper | Tutorial ]
Chan, Poon and Zhu (2026)
extend these ideas to time-varying parameter MIDAS state space models and apply them to nowcasting US real GDP.
Model Comparison
Comparing state space models requires the marginal likelihood or an information criterion, both of which involve integrating out the states. The papers below develop fast and accurate estimators of the marginal likelihood and of the deviance information criterion (DIC).
Marginal Likelihood Estimation with the Cross-Entropy Method
Joshua Chan and Eric Eisenstat (2015), Econometric Reviews, 34(3): 256-285
[ Journal Version | Working Paper | Code | Toolkit ]
Chan and Eisenstat (2015) estimate the marginal likelihood by importance sampling, with the importance density chosen by
the cross-entropy method. The draws are independent, so a smaller numerical standard error costs little additional
simulation. In applications to women's labor market participation and US macroeconomic time series, the estimator compares
favorably with existing estimators.
Bayesian Model Comparison for Time-Varying Parameter VARs with Stochastic Volatility
Joshua Chan and Eric Eisenstat (2018), Journal of Applied Econometrics, 33(4): 509-532
[ Journal Version | Working Paper | Code | Toolkit ]
Chan and Eisenstat (2018) develop importance sampling estimators of the marginal likelihood and the DIC for time-varying
parameter VARs with stochastic volatility, based on the integrated likelihood. With US data, most of the gains over a
constant-coefficient VAR with homoscedastic errors come from stochastic volatility: by both criteria, a constant-coefficient
VAR with stochastic volatility outperforms the more general model with time-varying parameters.
Fast Computation of the Deviance Information Criterion for Latent Variable Models
Joshua Chan and Angelia Grant (2016), Computational Statistics and Data Analysis, 100: 847-859
[ Journal Version | Working Paper | Code | Toolkit ]
Chan and Grant (2016) develop fast algorithms for computing the observed-data DIC, in which the latent variables are
integrated out, for a variety of high-dimensional latent variable models. In three empirical applications, the observed-data
DIC has much smaller numerical standard errors than the conditional DIC, which conditions on the latent variables.
On the Observed-Data Deviance Information Criterion for Volatility Modeling
Joshua Chan and Angelia Grant (2016), Journal of Financial Econometrics, 14(4): 772-802
[ Journal Version | Working Paper | Code | Toolkit ]
Chan and Grant (2016) propose importance sampling algorithms, based on fast band matrix routines, for the observed-data
likelihoods of a variety of stochastic volatility models. In a Monte Carlo study, the DIC based on the conditional
likelihood tends to favor overfitted models, and the DIC based on the observed-data likelihood performs well. The
application uses daily returns on the S&P 500 index.
Output Gaps and Trend-Cycle Decompositions
Unobserved components models also decompose output into a trend and a cycle. The estimates page publishes the output gaps of the two models below every quarter, and the models page explains how they differ.
A Bayesian Model Comparison for Trend-Cycle Decompositions of Output
Angelia Grant and Joshua Chan (2017), Journal of Money, Credit and Banking, 49(2-3): 525-552
[ Journal Version | Working Paper | Code | Toolkit ]
Grant and Chan (2017) compare widely used trend-cycle decompositions of output in a formal Bayesian model comparison. For
US quarterly real GDP, the best model is an unobserved components model with correlated trend and cycle innovations and a
break in trend output growth in 2007, after which annualized trend growth falls from about 3.4% to 1.2–1.5%. Real shocks
are more important than nominal shocks.
Reconciling Output Gaps: Unobserved Components Model and Hodrick-Prescott Filter
Angelia Grant and Joshua Chan (2017), Journal of Economic Dynamics and Control, 75: 114-121
[ Journal Version | Working Paper | Code | Toolkit ]
Grant and Chan (2017) reconcile two widely used trend-cycle decompositions of GDP: the correlated unobserved components
model, whose output gaps are small, and the Hodrick-Prescott (HP) filter, whose cycles are large and persistent. Embedding
the HP filter in an unobserved components model shows that the difference comes from how the stochastic trend is modeled.
The HP filter also assumes serially independent cycles, which the data reject; relaxing this assumption gives a fit
comparable to the correlated unobserved components model.
Non-Gaussian and Nonlinear State Space Models
Many models in macroeconomics and finance are nonlinear or non-Gaussian. The papers below estimate flexible stochastic volatility models and compare them with GARCH models. The trend inflation models are on the trend inflation page.
Estimation of Stochastic Volatility Models with Heavy Tails and Serial Dependence
Joshua Chan and Cody Hsiao (2014), in I. Jeliazkov and X.-S. Yang (Eds.), Bayesian Inference in the Social Sciences, 155-176, John Wiley & Sons, Hoboken, New Jersey
[ Working Paper | Code | Toolkit ]
Chan and Hsiao (2014) review the estimation of flexible stochastic volatility models with heavy tails and serial
dependence, and introduce efficient algorithms based on recent advances in state space simulation. The examples use
precious metal and foreign exchange returns.
Modeling Energy Price Dynamics: GARCH versus Stochastic Volatility
Joshua Chan and Angelia Grant (2016), Energy Economics, 54: 182-189
[ Journal Version | Working Paper | Code | Toolkit ]
Chan and Grant (2016) compare GARCH and stochastic volatility models on nine series of oil, petroleum product and natural
gas prices, including versions with jumps, volatility in mean, leverage effects, and t and moving average errors.
Stochastic volatility models generally compare favorably with their GARCH counterparts, and the stochastic volatility model
with moving average errors is the best model for all nine series.